Server health
Server health reports on the Nexus Telemetry Fleet server itself: whether anything is wrong with it now, and how much more load it can take. It is opened from the icon rail. Only users in the platform organisation can open it. The platform organisation is the one created at the fleet server’s first run, and it manages the fleet server. See Organisations.
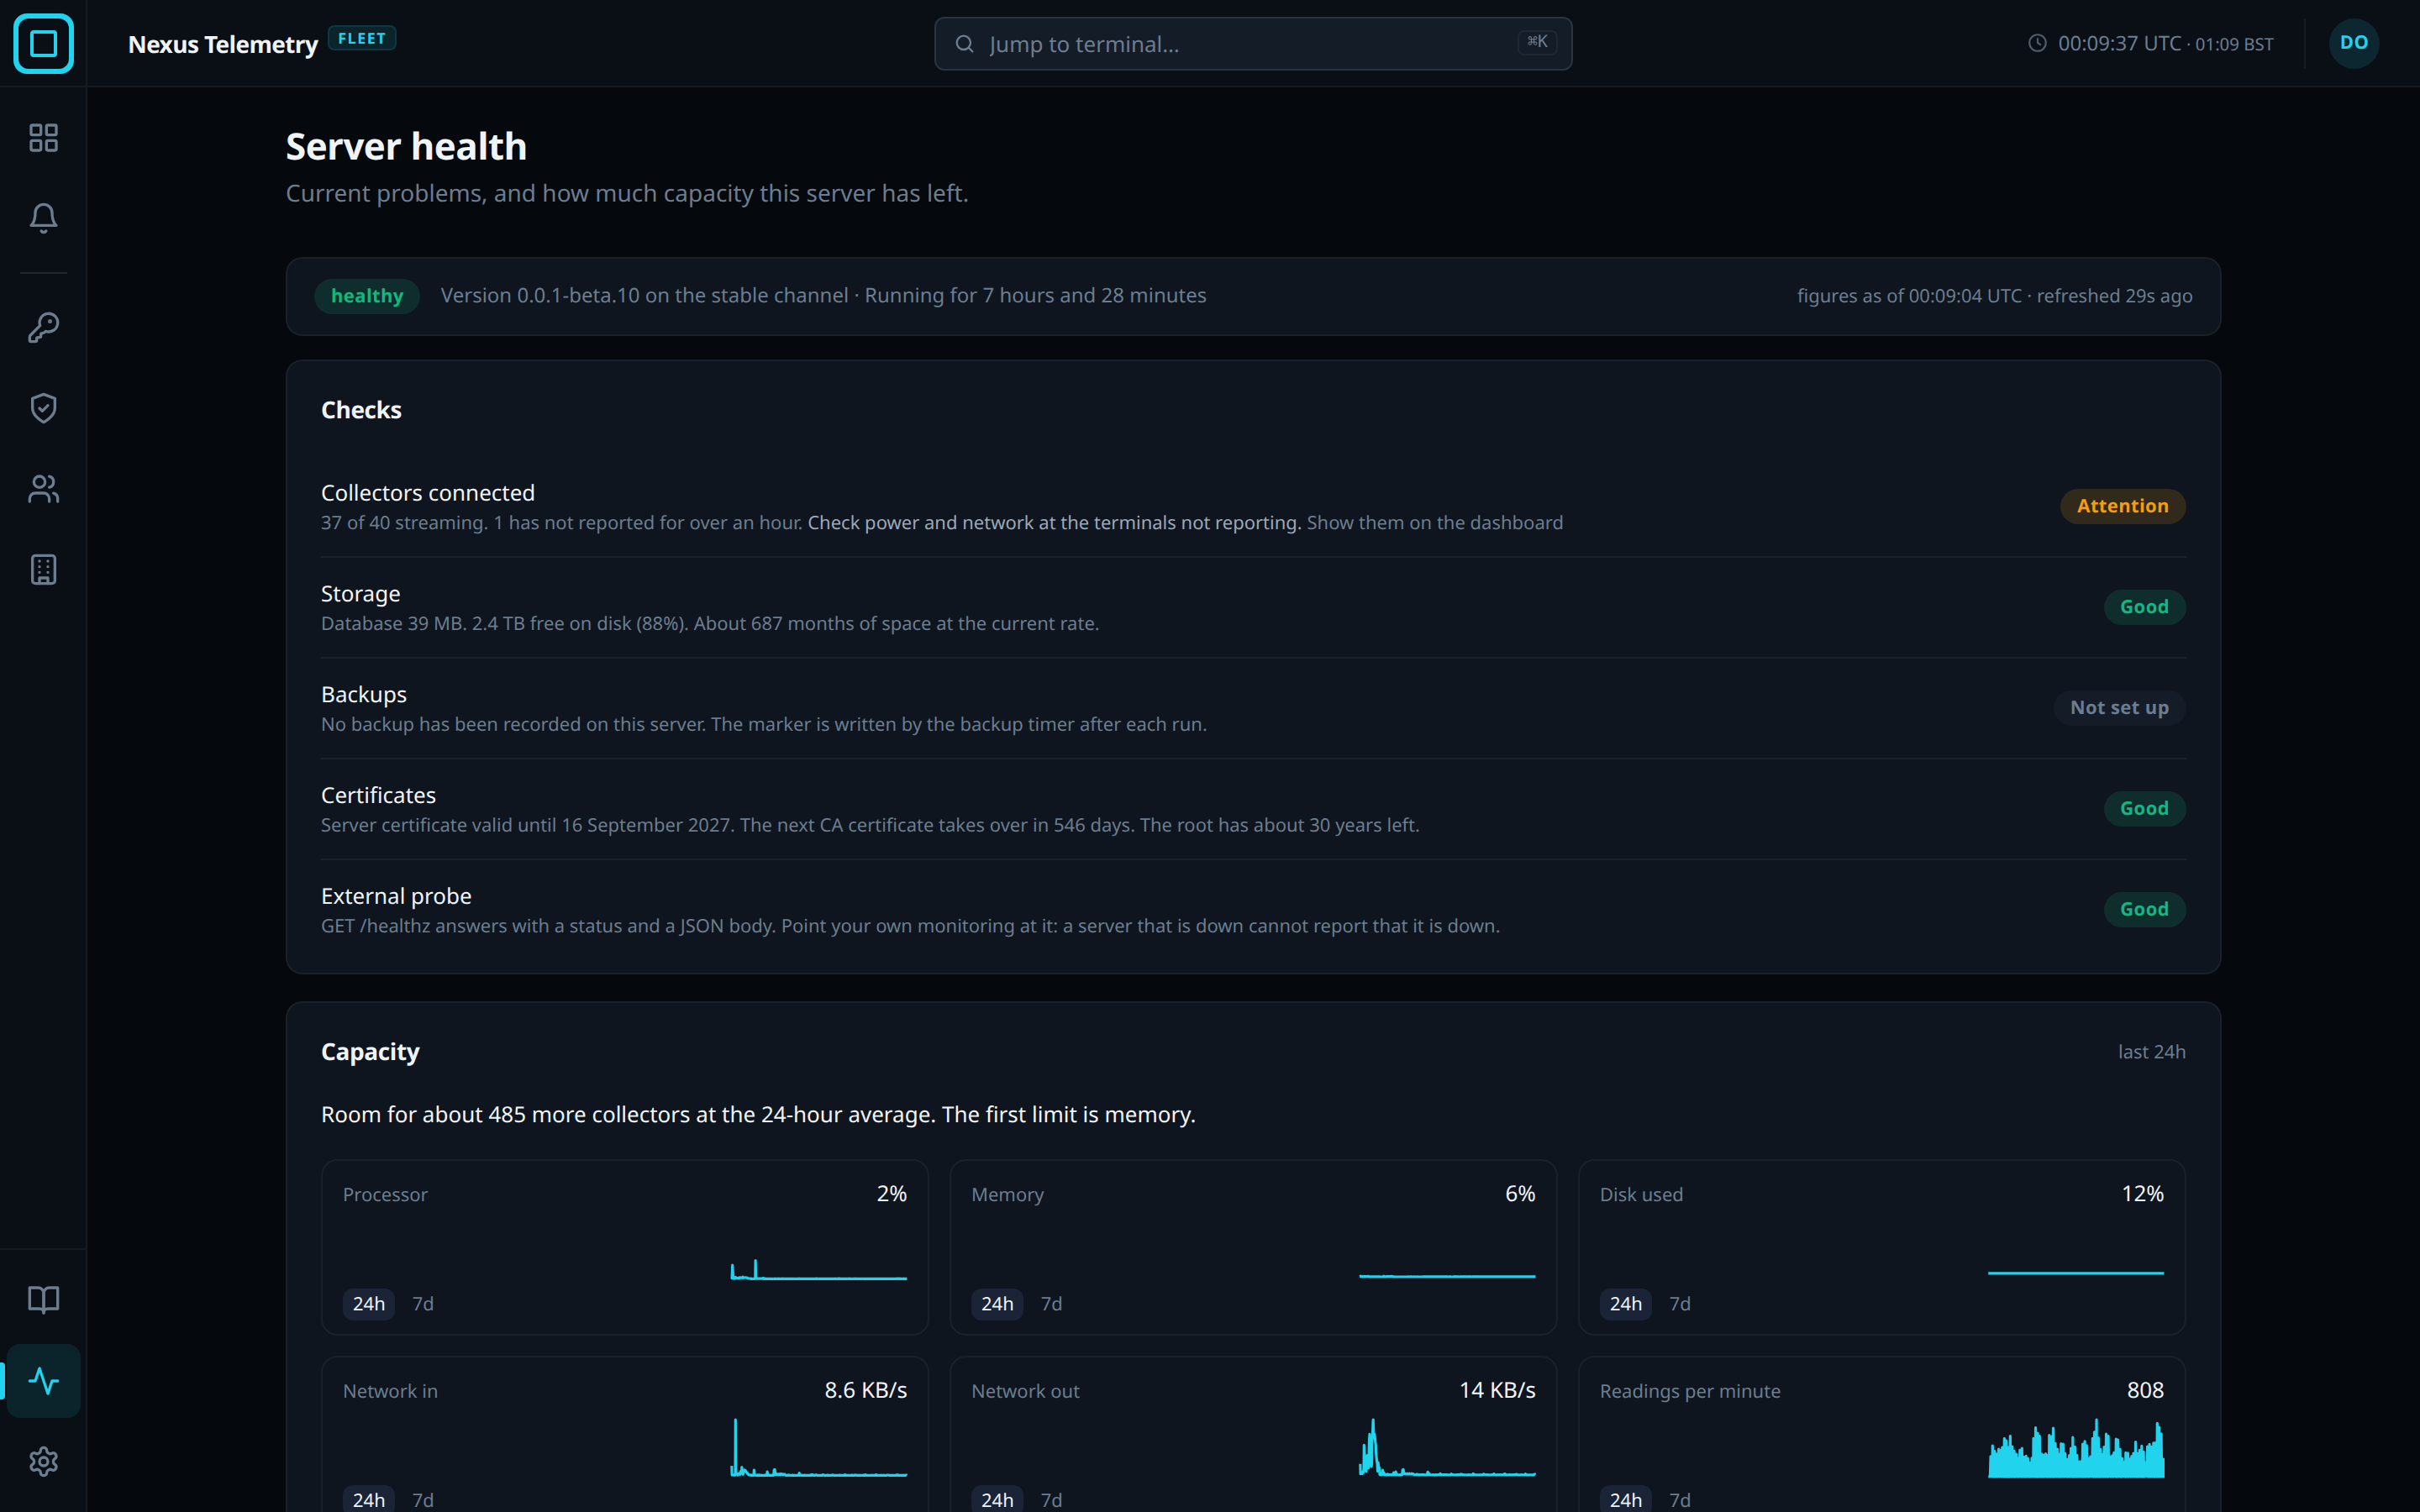
Headline
The page header gives the fleet server’s status, Healthy or Degraded, its Version with the release channel, and its Uptime. Updated gives the time the figures on the page were taken, in UTC. The header and the checks refresh every 30 seconds.
Checks
Each check has one sentence and a badge. Good, Attention and Problem grade the check. Unknown means the check could not be made, Not configured means the feature is not configured, and No data means nothing has happened to check. Where there is something to do, the sentence says what, for example Check power and network at the terminals not reporting. for collectors that have stopped reporting.
| Check | Reports |
|---|---|
| Collectors connected | How many collectors are connected, how many are enrolled, and how many have not reported for more than an hour. View on the dashboard filters the dashboard to the collectors in outage |
| Storage | The database size, the free disk space and its percentage, and when the disk is full at the current growth rate, in days, months or years, or more than 10 years |
| Backups | How long ago the last backup ran, or that no backup has run on this fleet server. A backup older than NF_BACKUP_MAX_AGE_HOURS, 26 hours by default, is marked |
| Continuous copy | Whether every database on disk is replicating to object storage, from the litestream counters at NF_LITESTREAM_METRICS_ADDR. Problem when a database has no replica running, litestream reported sync errors in the last 15 minutes, or litestream does not answer. Attention when a database is written and its replica has stopped advancing. Not set up without the variable |
| Certificates | How long the fleet server’s certificate is valid, when the next CA certificate takes effect, and when the root CA expires |
| External probe | That GET /healthz returns the status. With NF_PROBE_TOKEN sent as a bearer token it answers with the full JSON body. This is the address for monitoring from outside. See Private deployment |
Capacity
Capacity (Last 24 hours) gives how many more collectors the fleet server has capacity for at the last day’s average load, and the limiting resource. Processor, Memory, Disk used, Network in, Network out and Readings per minute each give their latest value and a line over 24 hours or 7 days.
Retention
Retention gives the retention policy in one sentence, then one row for each level of stored history: Raw readings, Five-minute summaries, Hourly summaries and Daily summaries. Each row gives the date of its oldest entry, its row count and an estimated size. A row reads Attention when its oldest entry is more than a day past the policy, or when fewer than 95% of the collectors that reported have a summary for its last 3 intervals. These figures are taken once an hour.
Size by tier charts each level’s size over time. Beneath it, one sentence projects the database size at 30 days, 90 days and 2 years at the last day’s growth. Database size by organisation lists the 10 largest organisation databases, largest first.
Degraded status
The fleet server reports Degraded in 2 cases only: its database is not
responding, or the pass that summarises readings has not finished for 3 hours. The
reason is given with the status. A check at Attention or Problem does
not by itself make the fleet server degraded. Collectors that stop reporting
are a problem in the fleet, not in the fleet server. GET /healthz answers
200 while the fleet server is healthy and 503 while it is degraded.
Measurement limits
A figure the fleet server’s host does not expose reads Not recorded on this host. rather than zero. The page measures the fleet server, not the network path to it, and a fleet server that is down cannot report that it is down. Monitoring from outside the fleet server’s network is what reports that. See Private deployment.